LLMs & Agents
AI assistants that answer customers, search company knowledge, and query databases in plain English, plus small in-house models that cut API bills and keep data private.
See 3 case studies →Principal Data Scientist · ML Engineer · Pune, India
For ten years I've turned AI ideas into products that ship and pay off: AI assistants that resolve real customer issues, AI video fast enough to sell, and ad pricing that runs on 50B+ requests a day. I lead a data science team at Talentica Software and advise companies on making AI work.
Now · Oct 2026 Leading a five-person team on AI agents and generative video. Open to Principal Data Scientist roles and select advisory work.
About
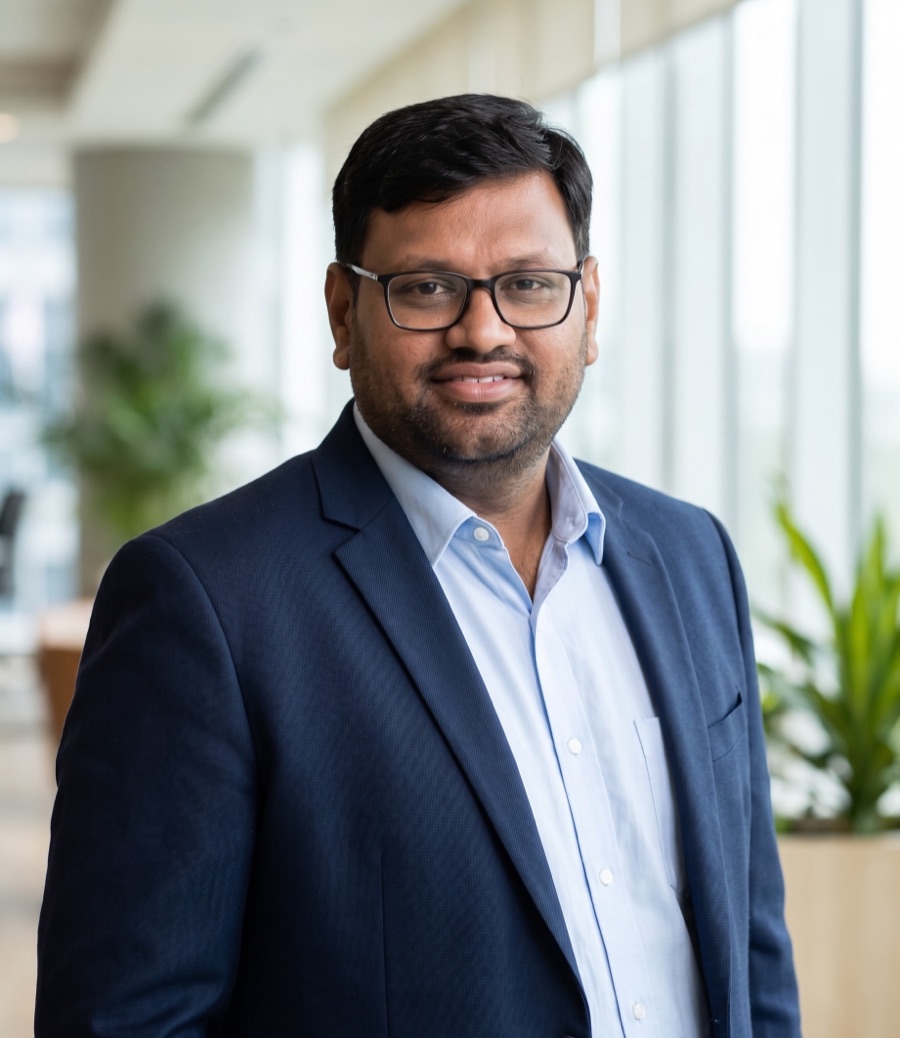
I'm a Principal Data Scientist with an M.Tech in Computer Science (Machine Learning) from the Indian Institute of Science, Bangalore. Over the last decade I've moved from backend engineering to leading ML end to end: framing the problem, picking the right model family, and owning latency, cost, and the metric the business actually cares about.
Today I lead a team of five data scientists building AI agents, small in-house language models, AI video generation, and real-time ad pricing. My work is deliberately broad: simple, proven models where they do the job, and frontier generative AI where nothing else will.
I want to keep growing as a Principal Data Scientist: setting technical direction for ML organisations, mentoring the next generation of scientists, and helping companies make sound, measurable AI bets. That's also why I take on selected advisory work.
Expertise
Pick an area to jump to the case studies behind it.
AI assistants that answer customers, search company knowledge, and query databases in plain English, plus small in-house models that cut API bills and keep data private.
See 3 case studies →AI video that animates a face or body from a single photo, and real-time vision that reads documents and tracks objects in live video.
See 3 case studies →Pricing and filtering decisions made in a millisecond at massive scale, plus forecasting and anomaly detection, all proven with live A/B tests.
See 3 case studies →The engineering that makes models fast, affordable, and reliable in production: multi-GPU serving, monitoring, and automatic retraining. It sits underneath all of the above.
See all case studies →Selected work
Each one started as a business problem, not a model. Open any tile for the challenge, approach, and results.
Ad Tech · Classical ML
Smarter ad pricing that earns more per ad while dropping traffic that was never going to pay.
Challenge Price ad inventory well and cut wasteful traffic across 50B+ bid requests a day from 100+ bidders, inside a hard latency budget.
CatBoost · Multi-armed bandits · A/B testing
Generative AI · Agents
An AI support assistant that resolves most customer conversations without a human.
Challenge Automate high-volume customer support without losing the safety net of human escalation.
LangGraph · LangChain · LangFuse
Generative AI · SLM fine-tuning
Replaced an expensive external AI service with small in-house models: candidate data stays private, at half the cost.
Challenge Replace a frontier-LLM system with self-hosted models to keep candidate data private, while holding quality and cutting cost.
Qwen3 · QLoRA · PEFT · vLLM · AWS
Generative Video · Emovid
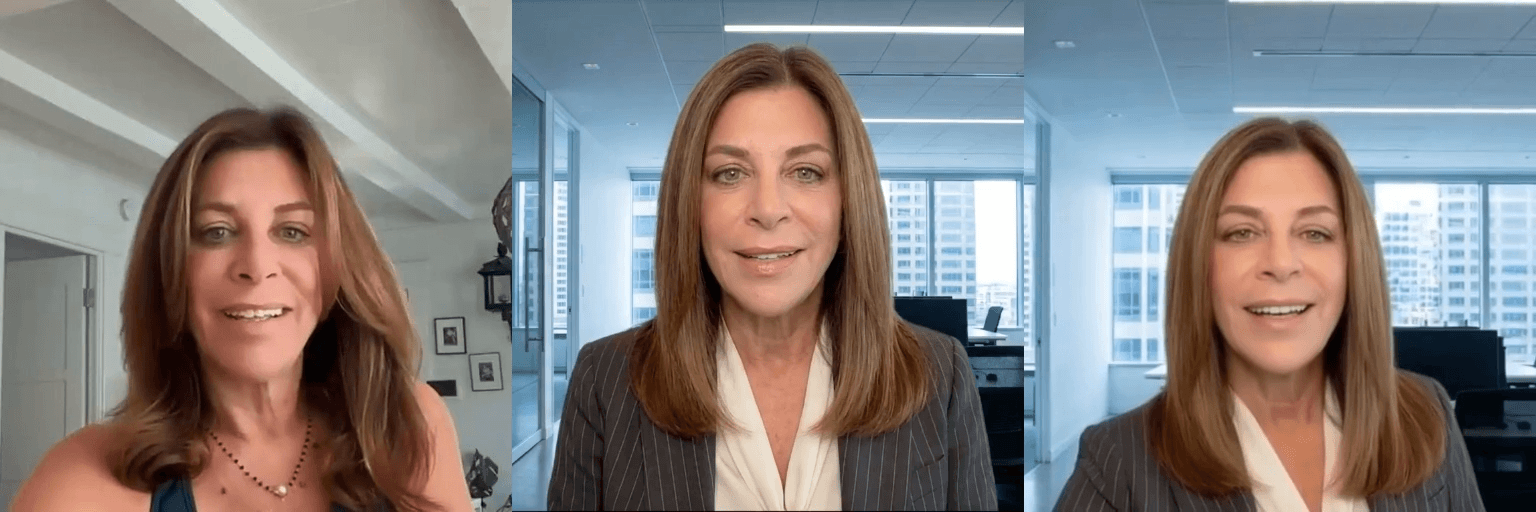
Turns a single photo into a realistic talking video, almost twice as fast as before.
Challenge Turn a single image into a realistic talking video, fast enough to be a product rather than a demo.
Diffusion models · Landmark detection · Multi-GPU inference · Frame interpolation
Generative AI · RAG
Lets business users ask questions of their databases and documents in plain English.
Challenge Let business users query structured data in plain language and search text, image, video, and audio knowledge in one place.
PGVector · BGE-reranker-v2 · PostgreSQL · LLMs
Computer Vision · Privacy
Straightens scanned ID documents and hides sensitive numbers automatically, in under a fifth of a second.
Challenge Correct document orientation and mask sensitive IDs in real time, where a single miss means PII leakage.
YOLOv8 · MobileNet · OpenCV
Classical ML · MLOps
A forecasting system that notices when its data changes and retrains itself.
Challenge Forecast performance from geographic, census, and demographic signals, and keep the model accurate as the underlying data shifts.
GCP AutoML · BigQuery · KS-test drift monitoring
Computer Vision · Video
Follows people and objects through live video while keeping track of which is which.
Challenge Detect and follow multiple objects across live video, keeping each object's identity consistent from frame to frame.
YOLO · DeepSORT · OpenCV
Citrix · Anomaly Detection
Flags real server problems while cutting false alarms by almost a third.
Challenge Flag genuinely abnormal server behaviour in Citrix Analytics without flooding operators with false alarms.
Isolation Forest · Python
Advisory
I work with founders, CTOs, and data teams who need a senior ML voice to get a decision right or a system into production. Every engagement is scoped around a measurable outcome.
Is this an LLM problem, a classical ML problem, or not an ML problem at all? A clear build/buy/skip call with cost and accuracy estimates.
Hands-on design and delivery, with evaluation and observability built in from day one rather than bolted on after launch.
Distilling frontier APIs into self-hosted models, multi-GPU inference, and serving optimizations for systems already in production.
Architecture reviews, experimentation design, and coaching so your team can run the system confidently after I step back.
Business goal, data, constraints, and the metric that defines success.
A fast baseline against an honest evaluation set before anyone scales anything.
Latency, cost, monitoring, and A/B validation in the real environment.
Documentation, dashboards, and a team that owns it.
“We have absolutely loved working with Alakh and he has been a cornerstone of our team, thanks so much!”
Oct 2019 – Present · Pune
Lead a team of five data scientists delivering production ML across LLM agents, generative video, and ad tech. See the case studies.
These are Talentica's official titles; its data science track uses "Software Engineer – Data Science". My current role is the equivalent of Principal Data Scientist.
Jul 2018 – Oct 2019 · Bangalore
Anomaly detection for Citrix Analytics (30% fewer false positives) and NetScaler features.
Jul 2013 – Jul 2015 · Jaipur
Java and MySQL backends, deployed on-premise for small businesses.
M.Tech, Computer Science & Automation (ML) · Indian Institute of Science, Bangalore
2016 – 2018
Research on multi-class imbalance and debiasing word embeddings. AIR 45, GATE 2016 (CS).
B.Tech, Computer Science Engineering · Rajasthan Technical University
2009 – 2013
Writing
Contact
For principal or leadership roles in data science, advisory engagements, or speaking and writing, send me a message here and it comes straight to my inbox.